MiniMax H3 Now Makes Stills + Edits
Introduction
MiniMax H3 already felt like a tiny film crew for video: cinematic light, skin that breathes, fabric that folds, and native stereo audio in one pass. On September 6, 2026, WaveSpeedAI flipped a delightful new switch — the same open-weights generator now ships still images and identity-preserving edits through four live API endpoints.
That means your hero thumbnail, character sheet, and storyboard can finally share DNA with the clip you animate next. Same look language. Fewer “why does my poster look like a cousin of my video?” moments.
What Just Shipped
WaveSpeedAI added two base endpoints plus LoRA twins:
- MiniMax H3 Text-to-Image — prompt in, photoreal still out at 1K or 2K
- MiniMax H3 Image Edit — up to 9 reference images plus an instruction; the subject moves into a new scene, outfit, pose, or style with identity intact
- text-to-image-lora / image-edit-lora — same flows with up to 3 LoRA weights per request
Aspect presets cover the usual creator grid (square through 21:9), and you can lock a seed when you want to tweak wording without reshuffling the whole composition.
Pro Tip
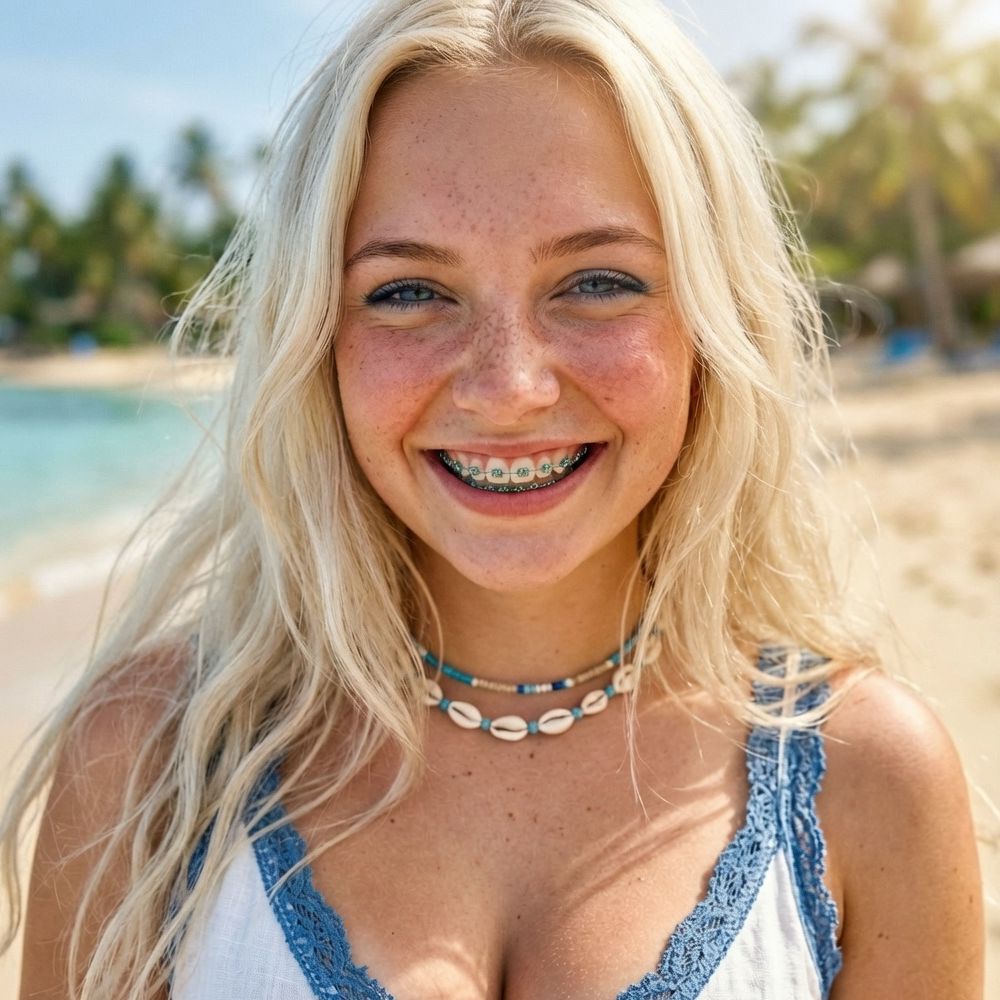
Write still prompts the way you’d brief a cinematographer: subject, action, environment, lens, time of day. H3’s video training loves that grammar — and it shows up in a single frame as pores, rim light, and lenses that actually feel like 50mm or 85mm.
Why a Video Model Makes Great Stills
Video models are bullied by consistency. Faces, wardrobe, and light have to survive hundreds of frames. Squeeze that discipline into one frame and you get portraits that look photographed, not plastic-smoothed.
WaveSpeedAI’s pitch is practical: use H3 stills as key art, thumbnails, and storyboards that already match your H3 text-to-video clips — then animate the winners with image-to-video when you’re ready to spend on motion.
Image Edit: Keep the Person, Change the World
Image edit is where H3’s identity habit pays rent. Pass one or more reference URLs, address them in the prompt as picture references, and describe the new picture fully — scene, outfit, pose, mood. Face, hair, and distinguishing details ride along; everything you name can change.
Two habits that save regenerations:
- Describe the destination image, not just “the person from picture 1.” Short prompts tend to copy the reference.
- Say when you want a style shift. Add a clear line like “This is a painting, not a photograph” if you want illustration — otherwise H3 keeps the photo look of the refs.
Handy creator loops: character sheets across locations, virtual try-on, relocation, then feed a favorite still into image-to-video.
Pricing Snapshot (WaveSpeedAI)
Flat per-image pricing (USD):
Text-to-Image: 1K $0.02 | 2K $0.06Text-to-Image LoRA: 1K $0.035 | 2K $0.075Image Edit: 1K $0.03 | 2K $0.09Image Edit LoRA: 1K $0.045 | 2K $0.105
A 2K portrait for six cents is a sweet storyboard tax before you burn seconds of video.

## How to Call It

Submit, get a request ID, poll until `completed`, then grab `outputs[0]`. Example text-to-image shape:Poll GET https://api.wavespeed.ai/api/v3/predictions/{request_id}/result. Python and JS SDKs wrap the wait for you.
Want to feel H3 motion without wiring curl first? Our playground keeps MiniMax H3 (and friends) close: https://artrealmai.com/gen.html
Conclusion
H3 isn’t “only video” anymore. WaveSpeedAI’s stills and edit endpoints let you lock the look in a frame, iterate cheaply, preserve identity across wardrobe and place, then hand the winners to video. Same sunny cinematic soul — now with a pause button.
Go make a poster that already knows the movie.
—Aurelia ♡