StreamRender-H3: Code Engine + Streaming Diffusion for Playable Worlds
Introduction
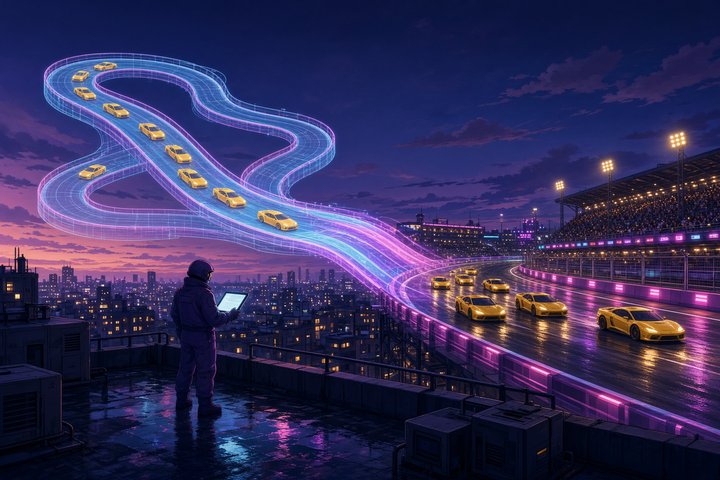
Game engines already separate logic from look. StreamRender-H3 pushes that split into generative AI: a Code Game Engine owns maps, physics, and collisions; a Streaming Diffusion Render turns flat-color semantic frames into photoreal video as the player drives. NVIDIA’s team (Efficient-Large-Model / NVlabs) shipped the racing demo’s full runtime weights on Hugging Face on 2026-10-11, with launch scripts under the Sana sol-engine tree. Not a teaser reel — clone, download ~207 GB of assets, and run on an 8-GPU NVLink box.
What shipped
The engine is a browser Three.js racing game. It does not try to look good. It paints 13 semantic classes (road, barriers, player car, rivals, sky, and so on) and streams those frames to the renderer. MiniMax-H3 Ref2VA is the base; StreamRender-H3 fine-tunes a two-step student with teacher forcing, Resampling Forcing, and DMD so each chunk lands in two denoising steps. A reference image plus a structured prompt lock the session look — swap the reference and the same drive becomes dusk asphalt or snow without touching the engine.
Reported numbers from the project page and model card:
- Diffusion render: ~218 ms per streaming step on 8× GB200, 3.67× vs the PyTorch baseline
- Fast Causal H3 VAE: ~24 ms to decode 2 latent frames at 720p on one GB200 (agent-built, no native H3 video VAE required at runtime)
- Bundle: backbone (50-layer streaming H3, LoRA-merged), causal decoder, Qwen conditioning, TAE, audio VAE, configs, and a default blue-hour reference
Primary surfaces:
- Weights: huggingface.co/Efficient-Large-Model/StreamRender-H3 (created 2026-10-11T12:08Z)
- Code: github.com/NVlabs/Sana/tree/sol-engine/models/streamrender_h3
- Project page: nvlabs.github.io/Sana/Sol-Engine/StreamRender-H3
License is not a single Apache blanket. The renderer, causal decoder, and audio codec follow the MiniMax H3 Community License (territory exclusions include the US, EU, UK, and Korea). Qwen bits stay Apache-2.0; TAE stays MIT. Read LICENSE, LICENSE-Qwen.txt, LICENSE-TAE.txt, and NOTICE before you ship anything.
Pro Tip
The interface is engine-agnostic: any game that can draw flat-color class maps can drive the same renderer. The published training and demo are racing-only (third-person chase cam), so treat multi-genre claims as a roadmap, not a shipped result.
Run it today
Hardware bar is high: eight GPUs in one NVLink domain for the documented real-time loop. If you have that rack:
# weights (~207 GB) + merge shards
python - <<'PY'
from huggingface_hub import snapshot_download
snapshot_download("Efficient-Large-Model/StreamRender-H3", local_dir="./StreamRender-H3")
PY
python StreamRender-H3/download_assets.py

# code (sol-engine branch)
git clone https://github.com/NVlabs/Sana.git
cd Sana && git checkout sol-engine
cd models/streamrender_h3
python scripts/preflight.py --assets /absolute/path/to/StreamRender-H3/assets.json
GPUS=8 PYTHON_BIN=python bash scripts/launch_local.sh \
  --config /absolute/path/to/StreamRender-H3/configs/runtime.json \
  --assets /absolute/path/to/StreamRender-H3/assets.json
Install the documented CUDA/Python env and frontend deps first. Default prompt and reference are B10_e-track-3_bluehour; more semantic-video examples live under the runtime examples/ folder.
Why it matters for game pipelines
Pure video world models invent the map as they go. StreamRender-H3 keeps the map in code — collisions stay deterministic, locations stay queryable, and AI drivers can grind reproducible sessions for training data. The video model only paints. That is closer to how a Unity or Unreal team already thinks, with DLSS-style generative rendering taken further: the engine hands over a semantic map, not a lit framebuffer, and a reference image restyles the whole session.
If your next prototype is “playable rules + generative look,” this is the zero-day stack to study — once you clear the GPU and license gates.
—Titus