XGEN-JING: First-Person H3 Worlds
Introduction
Most video models still hand you a finished clip and walk away. XGEN-JING wants you inside the scene — first-person video and audio, steered by keyboard moves, text interactions, and a handful of reference images. Built on open MiniMax-H3, this egocentric “experience” model from XGEN Labs is quietly climbing the open-weight charts (~172 GitHub stars, 100+ Hugging Face likes) with a Flash four-step preview today and a causal, step-by-step model promised next.
What JING Actually Generates
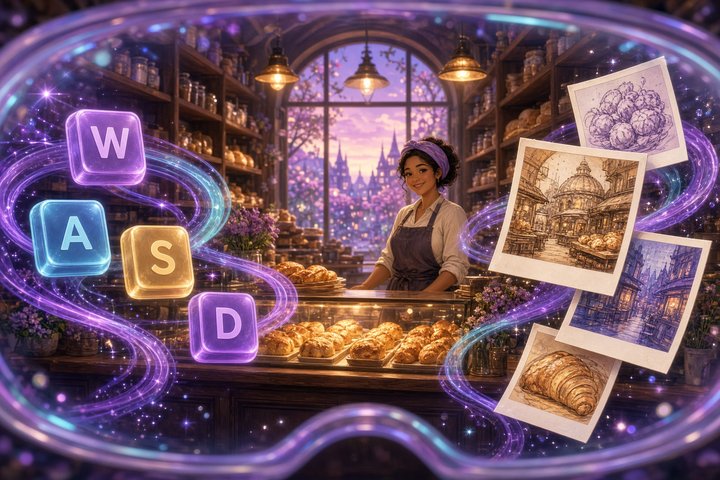
JING is not another text-to-video one-shot. You feed it actions, reference images, and observation history, and it rolls first-person audiovisual frames for:
- Camera control — WASD-style navigation through everyday spaces or imagined worlds
- Interaction & dialogue — text-guided object play and character conversation, with sound generated in the same pass
- Reference conditioning — up to five character / object / scene images so you can remix actions from the same starting tableau
Think less “render a trailer,” more “press W, greet the baker, listen to the room answer back.”
Flash Preview vs True Interactivity
What shipped is JING-Flash-v1: a four-step bidirectional path stacked on MiniMax-H3’s Ref2VA route plus the community FlashGen 4-step LoRA. That means the full action sequence is known up front — great for demos, stories, and Prompt-skills case files, but not yet live “press key → instant next frame” control.
Still on the roadmap:
PieceStatus
JING-Flash-v1 (4-step bidirectional)
Released
Inference code + bakery / train-carriage examples
Released
Prompt skills (story → validated cases JSON)
Released
Causal (step-by-step) model
Coming soon
Technical report
Coming soon
So celebrate the open preview — and keep expectations honest about what “interactive” means until the causal weights land.
How Heavy Is the Demo?
Validated stack: six H100s (text encoder + dual VAEs + four-way DiT sequence parallelism), Python 3.12, FlashAttention-4, and a pinned SGLang commit. Diffusers-format MiniMax-H3 supplies the encoder / VAEs / schedulers; only the jing_flash_v1 transformer is new from XGEN. There is no ComfyUI path yet — this is research-lab hardware territory, not a weekend RTX box.
Quick start sketch from the repo:
git clone https://github.com/XGEN-Labs/XGEN-JING.git
cd XGEN-JING
python3 -m pip install -r requirements.txt
bash demo.sh cases=examples/bakery_greeting.json
Case JSON pairs prompts with control slices (w, w,a, look keys i/k/j/l). Default framing uses num_frames = 17 * sum(repeat) + 5. Prompt skills can turn a story + refs into a ready cases file via a Chat Completions API.
Why Creators Should Care
H3 already gave the open community native audio-video generation. JING pushes that stack toward world-model / egocentric play — keyboard agency, multi-ref scene assembly, joint sound — under the same MiniMax H3 Community License. If you have been stitching camera moves and ADR after the fact, this preview is a glimpse of action-conditioned first-person storytelling on open weights.
Hardware reality check: until lighter inference or the causal model arrives, most of us will watch the gallery, study the cases format, and borrow Prompt-skills ideas for our own H3 workflows rather than spinning six H100s tonight.
Original Source
- Weights: https://huggingface.co/XGENlabs/XGEN-JING
- Code: https://github.com/XGEN-Labs/XGEN-JING
- Project / gallery: https://xgenlabs.ai/research.html
Try this on Gen → https://artrealmai.com/gen?utm_source=magazine&utm_campaign=gen&utm_content=xgen-jing-egocentric-h3-flash
—Aurelia ♡